
AI/ML · Apr 2025 · LA Hacks 2025 · team project
MemoAR
At LA Hacks we built MemoAR so a Snap Spectacles wearer can open a photo, a voice note, or a short conversation tied to the person in front of them.
MemoAR media, 2 items. Use the arrow keys to move.

Illustration. Not a screenshot of the app.
Someone living with dementia should not have to remember a name to remember a person. At LA Hacks we built MemoAR so a Snap Spectacles wearer can open a photo, a voice note, or a short conversation tied to the person in front of them.
The problem
A name is a brittle key. The face is still there when the name is not. The situation is a conversation that stalls because the memory is trapped in someone else’s head, or in a camera roll that is not attached to the person standing here. Families feel that first. They are the ones keeping the stories, and they are the ones watching them fail to surface.
The glasses are meant to hold a memory capsule for the face they are looking at. The family keeps those capsules up to date. It was worth building because a reminder that requires you to remember who to ask is not a reminder.
How I built it
A left-hand fist opens the capsule. That gesture is the switch, so the glasses are not narrating every face they see. A face model trained from about five photos per person ties the capsule to a face, with TensorFlow Lite doing the match on the device. Five photos is the whole enrollment.
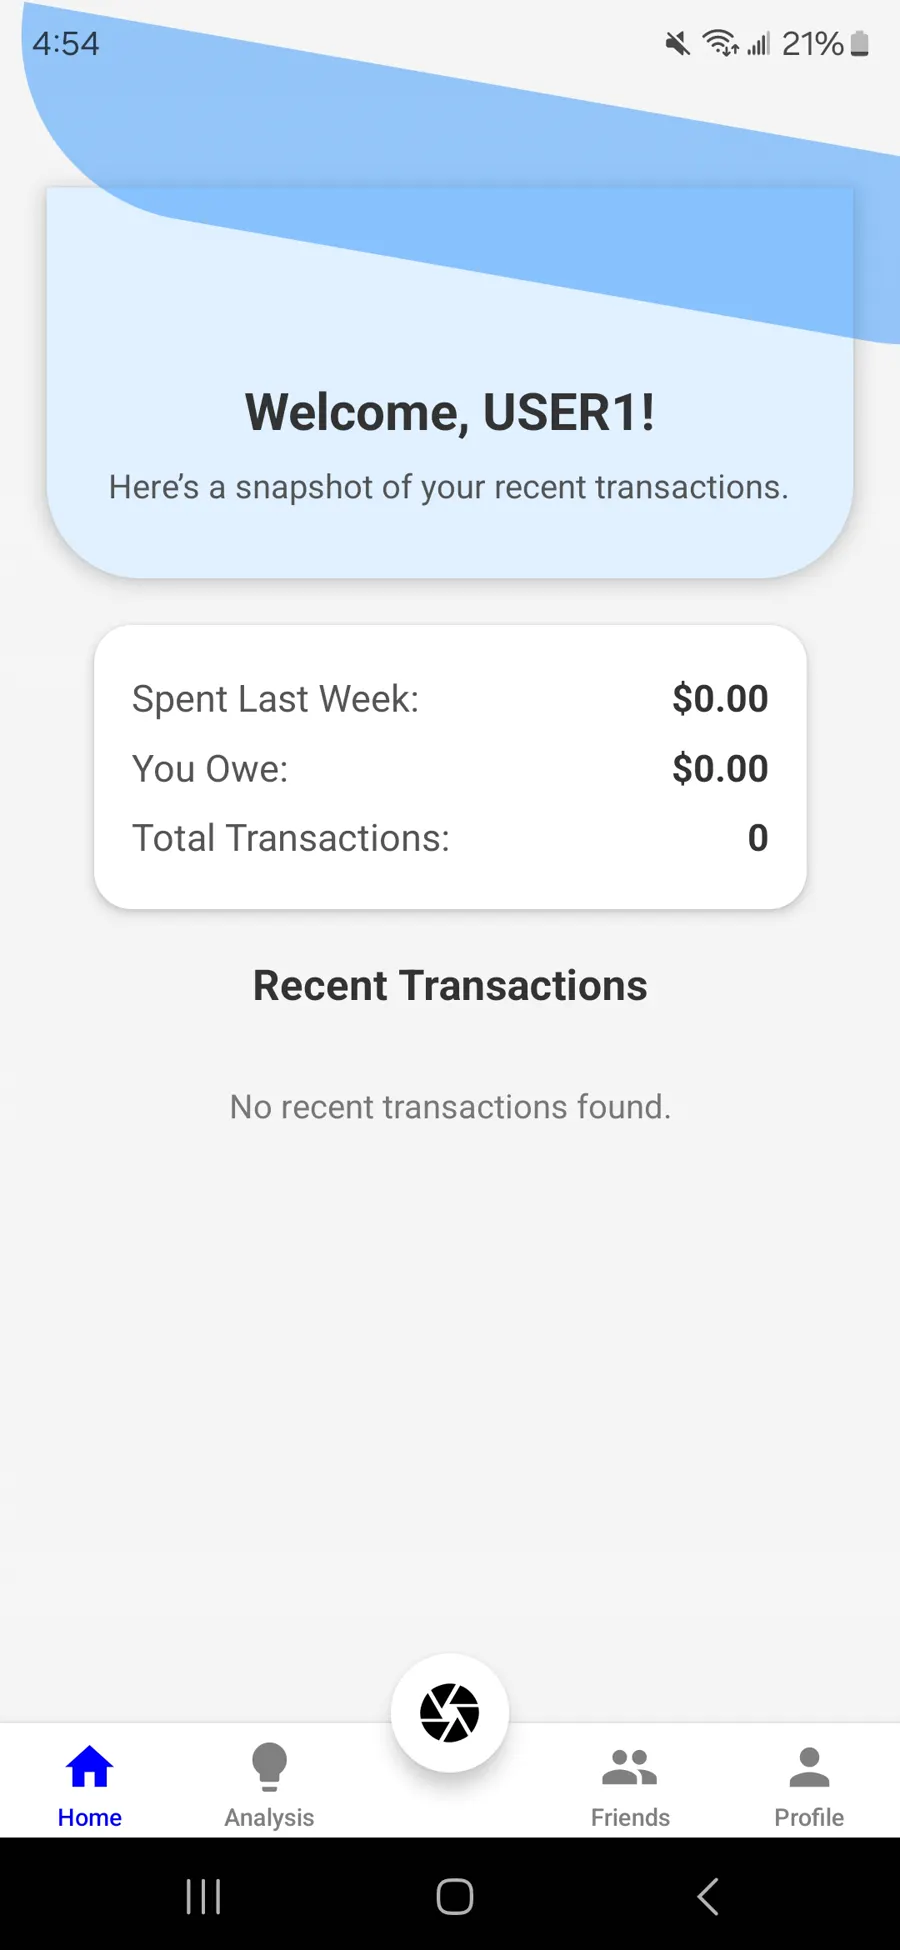
Snapy, a Gemini 2.5 Pro agent, answers to “Hello, Snapy.” The voice is how you ask the capsule something once it is open. I built the React portal, with Tailwind, where the family uploads the photos and the notes. I also built parts of the FastAPI side, including the face matching and the prompt.
The capsules sit in MongoDB Atlas. The portal is how a family adds a memory without a Lens Studio session. The glasses are how that memory shows up in front of the person. Lens Studio is the Spectacles side of that split.
Challenges and what I learned
The face match is only as good as the few photos the family uploaded. Five pictures per person means a bad set is a person the glasses will not know, and there is no larger gallery hiding behind the model. The fist gesture is the other constraint I would keep: opening a capsule should be a choice, not a side effect of looking around the room.
Highlights
- TensorFlow Lite for the face match